Foresight Iterative Reasoning About Clues that Matter for Navigation
1The University of Texas at Austin•2Field AI

1The University of Texas at Austin•2Field AI
Abstract
Open-world mapless navigation from sparse language instructions requires inferring which environmental cues matter — the ramp, sign, or detour that reveals where to go. Prior works draw cues from closed-set factor categories or identify them before motion planning, missing plan-dependent cues. Pretrained Vision-Language Models (VLMs) can discover such cues, but require adaptation to act on them.
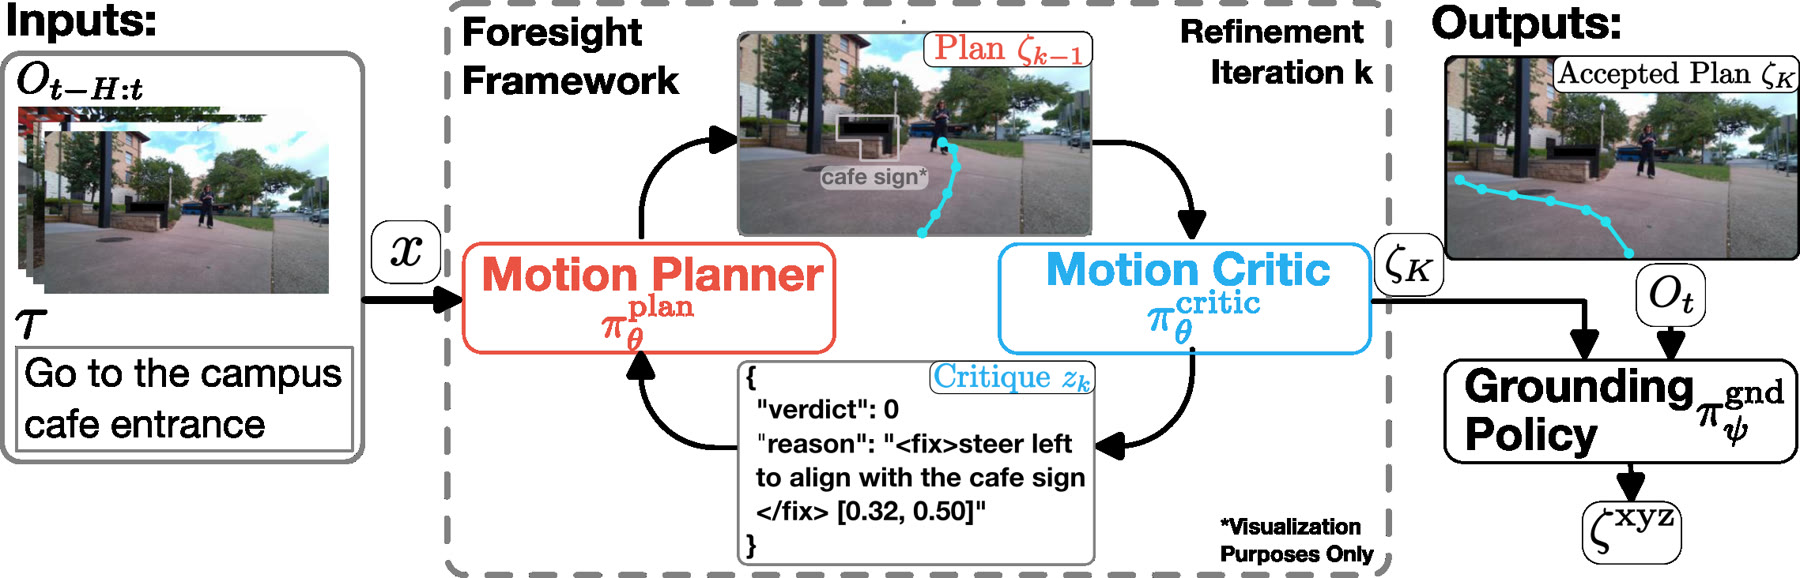
We present Foresight, a test-time framework in which a finetuned VLM alternates between proposing image-space motion plans and critiquing them against the language goal and visual context, conditioning each plan on prior critiques to refine its motion before execution. A reward model learned from human feedback post-trains the VLM with reinforcement learning inside this loop, aligning it with open-set behavior preferences. Across offline evaluations and 6 real-world environments, Foresight improves average task success by 37% and reduces interventions per mission by 52% relative to state-of-the-art test-time reasoning and foundation-model baselines, while running in real-time on a Jetson AGX Orin.
Approach
Foresight formulates motion planning as a test-time reasoning loop. Conditioned on the image observation and language instruction, a finetuned VLM proposes an image-space motion plan and then critiques it with respect to the language goal and visual context. Subsequent plans are conditioned on prior critiques, enabling the model to surface plan-dependent cues — ramps, signs, detours — and iteratively refine its motion before execution. A lightweight policy converts the refined image-space plan into executable trajectories.
Training
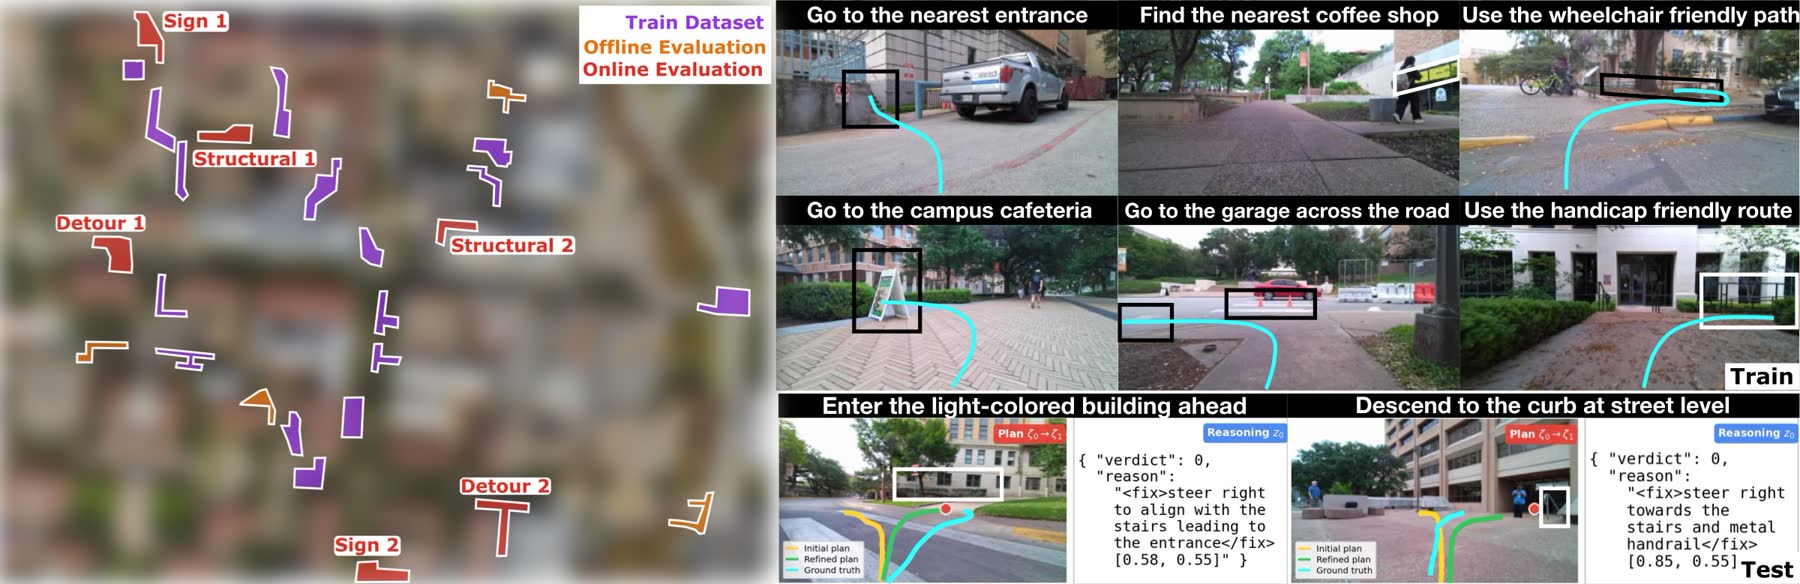
To adapt pretrained VLMs for iterative refinement, we propose a simple two-stage training recipe. We first apply supervised finetuning to teach the VLM the structure of the plan-critique loop. We then learn a reward model from human preference annotations to judge motion plan quality, and use it to post-train the VLM with reinforcement learning, aligning critiques and refinements with open-set behavior preferences that are difficult to capture with hand-designed objectives alone.
Domains
Training data, the offline benchmark, and the real-robot deployments are drawn from distinct geographic regions, so no test evaluation site appears in training. Instructions are collected the way an operator would phrase them: “go to the nearest entrance”, “use the wheelchair friendly path”, which leaves the relevant cue unstated and forces the model to determine what to look for.
Real-robot deployment
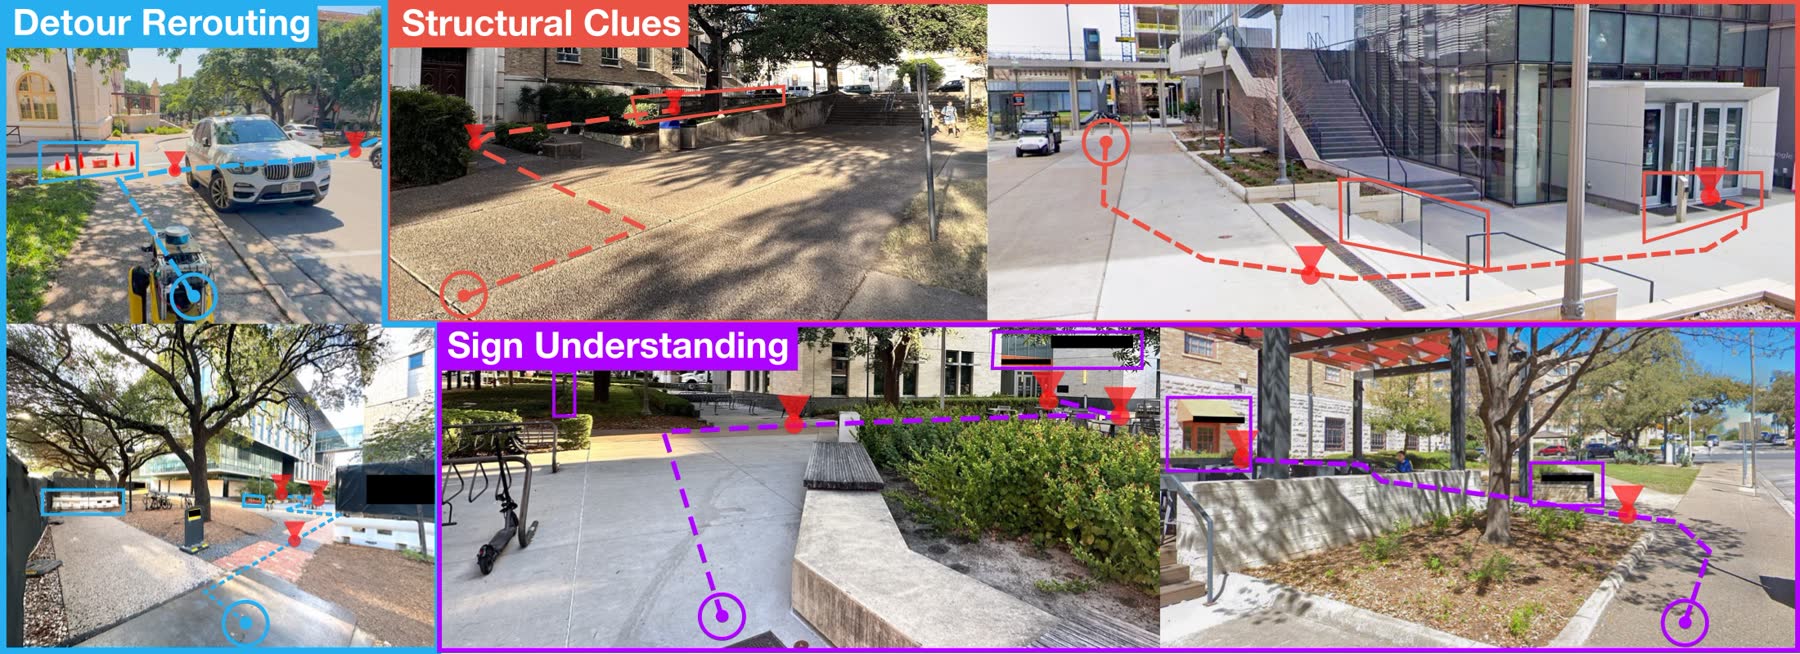
We deploy Foresight on a real robot and follow sparse language instructions in six environments held out from training, grouped into three families: detour rerouting, structural clues, and sign understanding. Each site is run against the same baselines, and an operator intervenes whenever the robot commits to an unrecoverable plan.
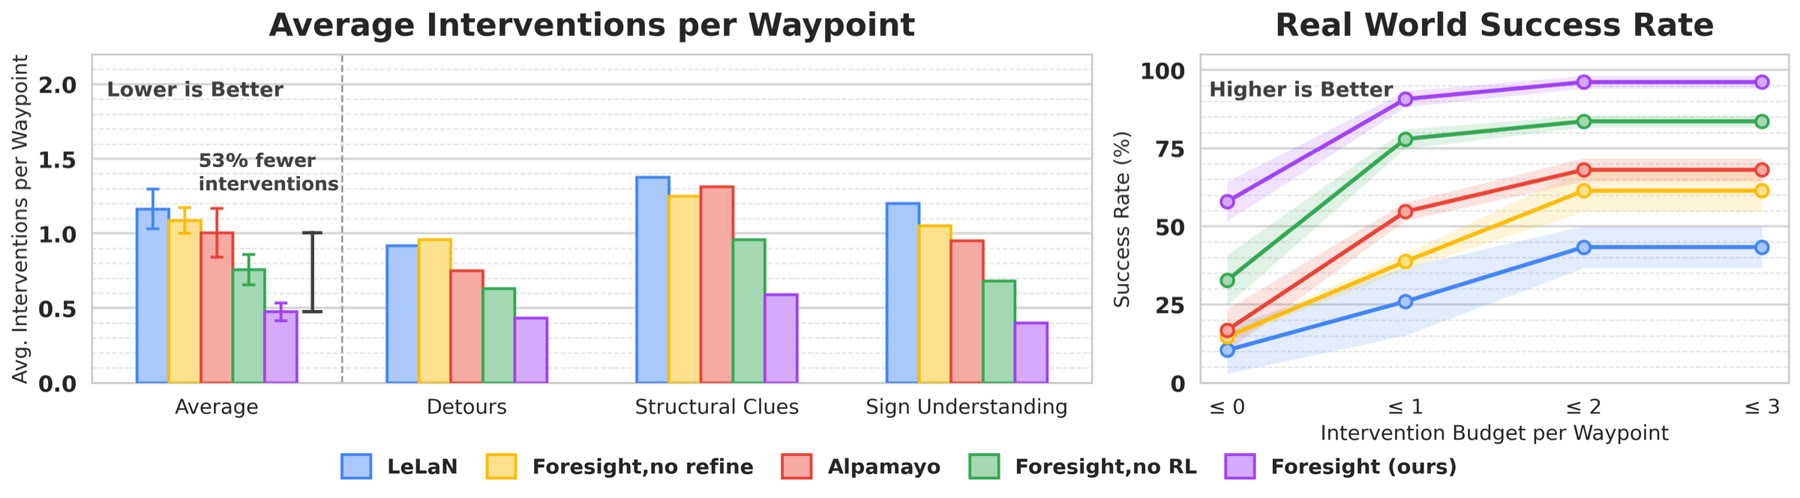
Both post-training steps matter on hardware, but refinement matters more. Foresight, no refine lands alongside the LeLaN and Alpamayo baselines, showing that a finetuned planner that never critiques itself behaves much like a feed-forward one. While Foresight, no RL outperforms all other non-refinement baselines. The margin is widest on structural clues, where the relevant evidence only becomes salient once the critic identifies the clue.
The success-rate curve provides a more deployment-centric view. With no interventions allowed, Foresight already completes more than half of the missions while every external baseline finishes under a fifth of them. Granting a budget of a single intervention per waypoint pushes Foresight close to saturation without closing the gap for the baselines, which still need multiple attempts to generate a valid plan.
Each clip runs LeLaN, Alpamayo, and Foresight on the same instruction and environment.
Detour rerouting tasks require inferring instruction-aligned alternative routes when the current path is blocked.
Offline benchmark
Offline, we score predicted image-space plans against human-demonstrated ones with the Hausdorff distance at 4 unique urban environments, which lets us isolate each design decision for larger models infeasible to run on the robot. We sweep the number of refinement iterations and compare against both general-purpose VLMs and robot foundation models, then ablate the reward design and the training configuration of the planner and the critic.
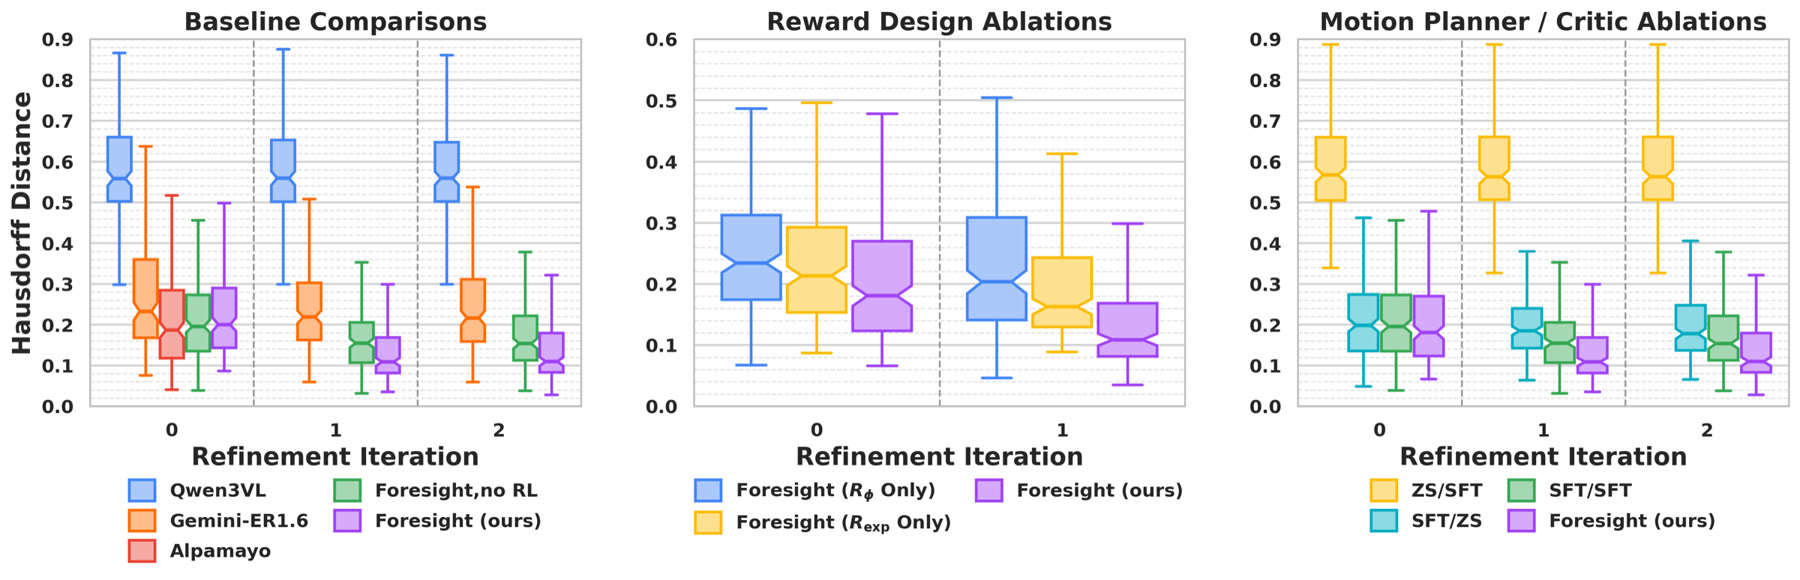
In the baseline panel, the general-purpose VLMs sit flat across refinement iterations as extra reasoning steps do not help a model that cannot tell a good plan from a bad one. Alpamayo, being feed-forward, has no refinement to give past the initial reasoning step. Foresight acheives the lowest-error method by improving from iteration 0 to 1, with most of the benefit realized by the first critique. Its error distribution is also visibly tighter, which is what thins out the tail of bad plans that force interventions on hardware.
Neither reward term alone reproduces the full model: training against either in isolation leaves a clearly higher median at both iteration counts, and only their combination shifts the whole distribution down. The planner/critic ablation makes a related point, but asymmetrically. A zero-shot planner (ZS/SFT) is catastrophic, with a median error several times that of any adapted variant — a good critic cannot rescue plans that were never plausible. A zero-shot critic (SFT/ZS) is far less damaging and lands close to finetuning both (SFT/SFT), which is why reinforcement learning on top of SFT/SFT, rather than supervised finetuning alone, is what produces the final margin.
Limitations
While Foresight makes significant strides toward scalable mapless navigation, several challenges remain:
Citation
@article{zhang2026foresight,
  title   = {Foresight: Iterative Reasoning About Clues that Matter for Navigation},
  author  = {Zhang, Arthur and Qi, Carl and Su, Donne and Meng, Xiangyun and Zhang, Amy and Biswas, Joydeep},
  journal = {arXiv preprint arXiv:2606.12550},
  year    = {2026},
}